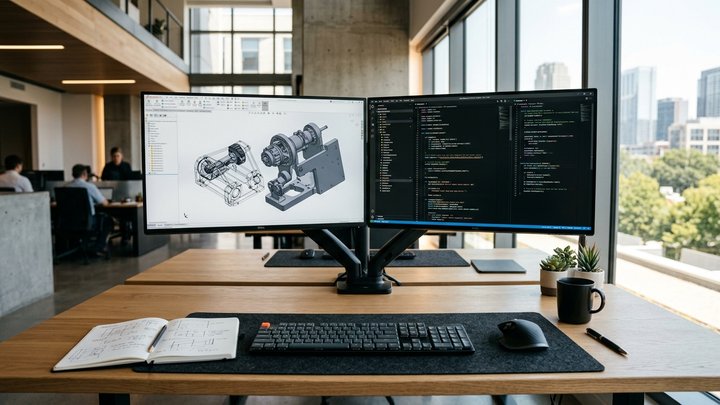
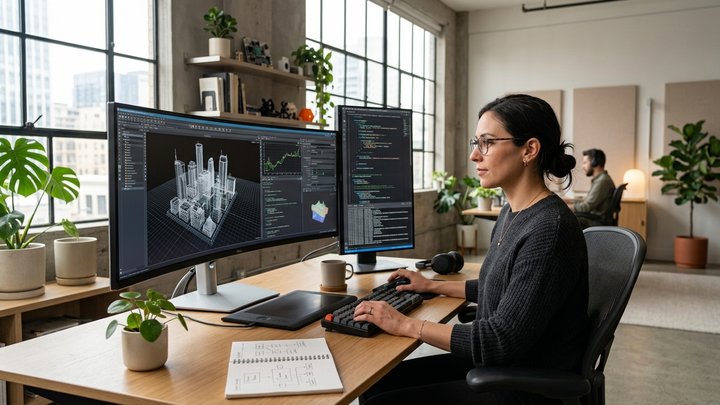
This workflow is mainly single-threaded which is why we recommend fast turbo frequency and lower core count.
Project complexity and multi-tasking determines the amount of RAM needed.
Website Under Maintenance and development not yet final
Find the ultra-light business laptop that fits your daily productivity with 45+ TOPS integrated NPU acceleration.
See how local LLMs, stable diffusion image generation, and enterprise security work seamlessly behind the scenes.
Take a detailed walkthrough into dual-socket Intel® Xeon® and quad NVIDIA RTX 6000 Ada workstation power.
Find the right high-density rack server node engineered for enterprise AI datacenter deployment and cluster scaling.
Find certified hardware platforms engineered to integrate smoothly with your developer environments, simulation software, and enterprise tools.
Explore →
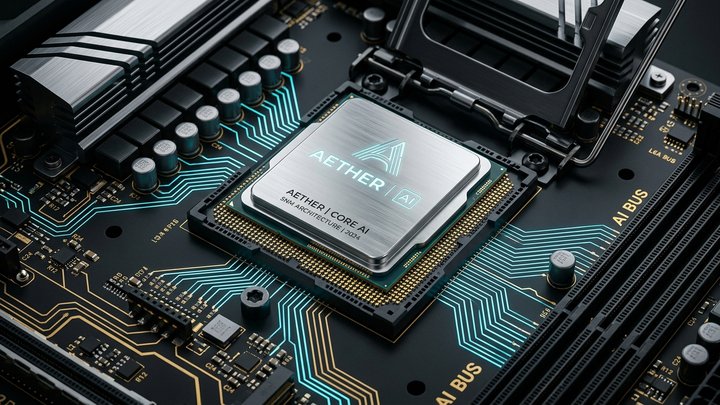
Harness next-generation silicon, dedicated NPU neural accelerators, and high-throughput PCIe Gen5 architecture.
Explore →
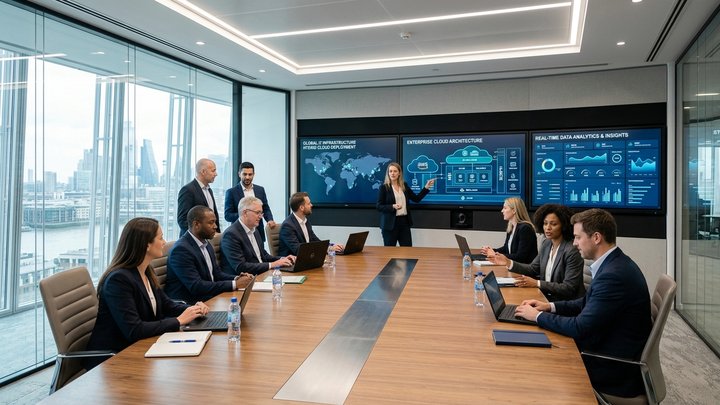
Receive strategic institutional guidance on enterprise computing tailored to your organizational goals and industry scale.
Get Guidance →
Accelerate productivity with purpose-built systems calibrated for your specific day-to-day workflow—from mobility to multi-GPU clustering.
Find out →Hardware sizing matrices engineered for single-threaded throughput, multi-threaded rendering, and high-density GPU acceleration.
This workflow is mainly single-threaded which is why we recommend fast turbo frequency and lower core count.
Project complexity and multi-tasking determines the amount of RAM needed.
Prioritize more cores if your software app takes advantage of CPU-compute and higher frequency if the app takes advantage of GPU-compute.
Model size and complexity determines the amount of RAM needed.
This is a multi-threaded workflow – meaning it takes advantage of all CPUs available – which is why we recommend prioritizing higher core count.
Project complexity and multi-tasking determines the amount of RAM needed.
Hybrid performance and efficient core architecture paired with 45+ TOPS neural processing for local AI execution.
Project complexity and multi-tasking determines the amount of RAM needed.
This workflow is mainly single-threaded which is why we recommend fast turbo frequency and lower core count.
Project complexity and multi-tasking determines the amount of RAM needed.
An architectural breakdown into hardware tensor cores, unified memory bandwidth, and zero-latency local LLM inference across business workloads.
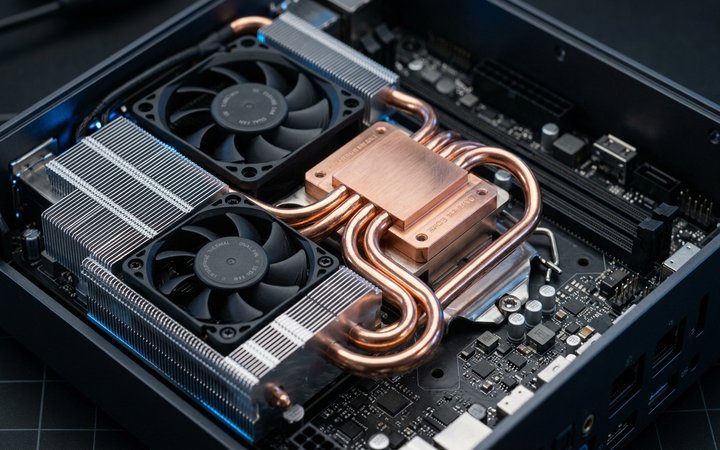
How dual vapor-chamber heat pipes and copper fin arrays dissipate 65W TDP silently in micro commercial form factors.
A network of 14 schools in Pune deployed OMBASE desktop fleets cutting 32% TCO with uninterrupted exams and local telemetry support.
The Union Cabinet clears landmark production-linked incentive scheme targeting ₹4.56 trillion in local tech manufacturing output.
Get official enterprise hardware quotes, bulk government procurement specs, RFP pricing, and tailored custom configurations for your organization.
Reach our 24/7 technical customer desk for official driver downloads, BIOS updates, warranty SLA registration, and 4-hour on-site dispatch servicing.